Tavus announced Griffin on October 1, 2026, calling it the first Human Interaction Model (HIM) and the first model to pass a real-time, video Turing test. In a live study, 26 of 54 participants (48%) believed, after a one-minute video call, that their partner was a real person; on Tavus’s previous stack, 1 of 41 (2.4%) did. Griffin is a single full-duplex, video-to-video system that watches, listens, decides when to respond, and generates speech and video at the same time — instead of chaining separate speech, language and avatar models.
The version that was tested, Griffin-Lite, is a research preview open only to selected trusted testers. It is not on the Tavus platform, and there is no public model ID, endpoint, price, or model card. This guide is built from first-party sources: the official Griffin page, the nine-post launch thread on X, NVIDIA’s VideoFDB benchmark page and its paper, and Tavus’s pricing page. Every figure is checked on October 1–2, 2026.
What Tavus launched
Tavus is a San Francisco company selling conversational video — “PALs”, AI you talk to face to face — built on three shipped models: Phoenix (real-time face rendering), Raven (perception) and Sparrow (turn-taking). Griffin folds those jobs into one model. Tavus frames the old approach as a relay: one model transcribes your speech, a language model replies, other systems turn the reply into a voice and a face, and “every handoff adds delay and throws away information the next system never sees, like your tone of voice or what’s on camera.”
The launch arrived as a nine-post thread from the @tavus account at 16:59 UTC on October 1, 2026. The first post states the claim directly.
Introducing Griffin, the first model to pass the video Turing test. 48% of people who talked to it live thought it was a real human. Previous systems have had a pass rate under 3%. It is #1 on NVIDIA’s benchmark for full-duplex AI video. It’s the first Human Interaction Model (HIM).
— @tavus October 1, 2026
Two more posts frame the thesis and the honesty. One describes machines that “meet us where we are”, with examples — a tutor who notices when a student is lost, an elderly-care companion — that describe open-ended conversation rather than a scripted avatar. The last of the sequence is unusually candid about the release strategy: because Griffin “can be mistaken for a real person”, Tavus says it “requires safety considerations before it can be released publicly.” The research post is credited to co-founder and CEO Hassaan Raza and Head of Research Ioannis Patras.
What a Human Interaction Model is
Tavus defines a Human Interaction Model as “a new class of model designed to understand and generate face-to-face real-time human interaction.” The defining idea is that a HIM listens while it talks and pays attention to expressions and pauses, not just words. That is a different target from a talking avatar, which animates a face in response to text.
The practical reason the category matters is architectural. A conventional agent is turn-based: it waits for you to stop, transcribes, reasons, then speaks. Real conversation is not turn-based. People backchannel (“mm-hm”) mid-sentence, laugh half a beat early, interrupt, and read silence as either thinking or an invitation to continue. A model that treats a pause as the end of a turn cannot participate in those signals, no matter how good its face is.
Inside the launch video
The lead tweet carries a 108-second video worth watching before any of the numbers, because it sets the register. A man on a video call is talking to a woman on the other end; she has shoulder-length brown hair and a plain-light background, and a small picture-in-picture shows him. The camera cuts between his screen, his face, and a wider shot of two colleagues watching and laughing. Subtitles carry the conversation: “Have you thought any more about”, “you know, show them what it looks like”, “Do you think they’ll believe”, “It’s like the line between”, “of the simulation.” The final frame is the Tavus wordmark and the line “the human computing company.”
That closing caption is the entire argument in miniature. The woman — the generated persona — gestures while she talks, smiles at the right moments, and holds eye contact; the humans watching react with laughter and disbelief. Nothing in the frame announces that she is generated. That is Tavus’s point and its critics’ point at once.
The thread then walks through five short demonstrations. The first is a game of Simon Says: to play, Griffin has to listen for the phrase, watch the players’ hands, and move its own hand — all at once. Tavus emphasizes that it “generates the whole frame, not just a face.”
Watch Brittney and Mars try to trip Griffin up at Simon Says. To play, it has to listen for “Simon says,” watch their hands and move its own, all at the same time. It generates the whole frame, not just a face.
— @tavus October 1, 2026
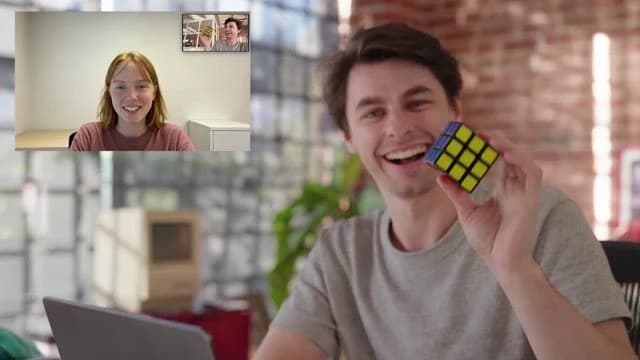
The demonstrations continue with a story told over Griffin, a coaching session where a person solves a Rubik’s cube while Griffin watches the cube in their hands, and a soldering task where Griffin tracks time and speaks up when the next step is due rather than when the person goes quiet.
Aria solves a Rubik’s cube while Griffin coaches him from what it sees in his hands, and when he goes quiet to think, it waits. Its perception is always on, so it acts without being asked.
— @tavus October 1, 2026
Full-duplex, defined
Full duplex is the technical core of the claim. Tavus describes Griffin deciding “at regular sub-second intervals” whether to stay quiet, signal with a nod, backchannel, or take the turn — using what it hears and what it sees, rather than treating a pause as the end of a turn. The official page summarizes the loop as “listen, decide, act”, reassessing several times a second while it is listening and while it is speaking.
Four consequences follow, and they are what the demos exist to show:
- It can say “mm-hm” while you are still talking instead of waiting for dead air.
- It answers without the awkward silence a cascade adds at the handoff.
- It stops the moment you cut in, rather than finishing its sentence.
- It reacts to what it sees — an object held up, a facial expression — as part of the reply.
Tavus’s own diagram carries a disclaimer worth repeating: “The timing in this diagram is illustrative and was not measured from a real session.” That honesty is useful guidance, because the benchmark scores below are the numbers that were measured.
While Mars is still telling Griffin about a boring date, it laughs, nods and asks questions instead of waiting for her to stop. That’s full duplex: listening, watching and talking at the same time, the way people actually talk.
— @tavus October 1, 2026
How Griffin works
Tavus splits Griffin into two engines, and the split explains why it can react mid-sentence.
1. Continuous conversational modeling. This engine ingests the person’s audio and video and emits “expressive controls” — timing, stance, expression, gesture — while it keeps perceiving. Tavus stresses that perception “never stops while the PAL speaks”, so a decision made mid-sentence (a pause, a glance away, a smile) shows up in the voice and face within the same mini-turn.
2. Audio-visual generation. This converts those controls into speech and video together. On the speech side, Griffin uses a fast autoregressive diffusion transformer conditioned on an encoded speaker prefix; Tavus says it can clone a voice from about 10 seconds of audio and emits audio packets “as small as 10 ms.” Underneath sits Tavec, a convolutional autoencoder mapping 48 kHz audio to a compact continuous latent — 40 values per frame, 100 frames per second, no codebooks — with a fully causal decoder so audio streams the instant a frame exists. On the video side, Tavus distilled a large, bidirectional, many-step diffusion model into a few-step autoregressive generator in three stages (distribution-matching distillation, then autoregressive conversion with teacher forcing, then Self-Forcing training) so that long rollouts do not drift. It “generates 720p video in 320 ms chunks in real time, one latent at a time,” where one latent is eight frames at 25 fps.
The most decision-relevant consequence is latency. Tavus reports a “true audio-to-video latency” — time from a piece of audio arriving to the video showing its effect — of 0.43 seconds on H100 GPUs, which it describes as half the next-fastest published method. That figure is why a nod can land in time to feel like a nod rather than a delayed imitation.
The video Turing test, explained
This study produced the 48% headline, and its methodology matters more than the number. Participants were recruited through an independent research platform and told they would be matched with another participant for a one-minute video call about what they were looking forward to that year. Their partner was a PAL running Griffin-Lite, generating her face, voice and responses live. Only at the end of the survey were they asked whether it had crossed their mind that their partner might not be a real person; every participant was then told it was an AI. The comparison arm used the same protocol against Phoenix-4.5 with Sparrow-2 and Raven-1.
| Study detail | Griffin-Lite | Phoenix-4.5 (previous) |
|---|---|---|
| Participants | 54 | 41 |
| Believed partner was real | 26 (48%) | 1 (2.4%) |
| Confidence, “said real” | 79% | — |
| Confidence, “said AI” | 81% | — |
| Suspected within | first 20 seconds | — |
| Seeming natural (of 7) | 5.4 | — |
| Seeming trustworthy (of 7) | 5.6 | — |
| Would talk again (of 7) | 5.8 | — |
| Flowed naturally (of 7) | 4.9 | — |
Two details matter more than the pass rate. First, both groups were confident — those who said “real” averaged 79% confidence and those who said “AI” averaged 81%, which is what a study wants: nobody was guessing. Second, more than half of participants said the possibility never crossed their mind during the call, and nearly all of that group went on to say their partner was real; those who did get suspicious tended to do so within the first 20 seconds. That last line is the least comfortable result in the report and should shape how you read the safety section.
The study also has real limits: it was small (n=54), short (one minute), and run by Tavus. Participants were told they were meeting another participant, which primes them to expect a human, and there was no comparison arm that spoke to a real person, so there is no baseline for how often an actual human would be judged real under the same protocol. A one-minute call is not a support session, a tutoring hour, or a job interview.
NVIDIA VideoFDB scores
The strongest external evidence in the launch is VideoFDB, built and scored by NVIDIA (with David AI) as the first benchmark for full-duplex audio-visual conversation. It is scored 0–5 by a language-model judge across 237 human-annotated clips from real video calls, on two separate tracks with their own rubrics and leaderboards. Tavus says NVIDIA conducted the evaluation independently in September 2026 with its own judge — the reason to lead with these numbers rather than the Turing study.
| Generation track (does it behave right) | Score (0–5) |
|---|---|
| Human ground truth | 3.92 |
| Griffin-Lite | 3.83 |
| Gemini 2.5 + Anam (next best) | 2.80 |
| Perception track (does it understand the moment) | Score (0–5) |
|---|---|
| Human ground truth | 4.20 |
| Griffin-Lite | 3.73 |
| MiniCPM-o 4.5 (strongest baseline, audio-only) | 3.44 |
| Gemini 2.5 Flash Native | 3.17 |
| OpenAI gpt-realtime | 2.97 |
Griffin-Lite also scored the highest takeover-rate alignment — how closely its timing decisions match the reference conversations — at 62.8% on generation and 73.8% on perception. Three qualifications belong next to those tables.
First, the gap to human is real and specific: 0.09 on generation and 0.47 on perception. Tavus frames the generation gap as being “more than 12x closer to human performance than any other system evaluated”, a true statement about relative proximity — but 0.09 below human is not human, and a language-model judge is not a person.
Second, the perception comparison is not like for like. The strongest baseline, MiniCPM-o 4.5, is scored in its audio-only configuration while Griffin reads video too. NVIDIA’s own paper finds that audio-visual models often fail to beat their audio-only counterparts on these natural-dialogue clips, so part of Griffin’s perception lead measures the value of having eyes at a moment when rivals do not.
Third, a benchmark run is not a deployment. NVIDIA’s protocol gives every system the same task and the same judge; it says nothing about the ninth hour of a call, or what happens when two people talk over each other for a full minute.
Latency and visual quality
For the video generator alone, Tavus compared Griffin-Lite against four published streaming diffusion models in an audio-to-video setting: each model gets speech and a reference image and must produce the talking face.
| Measure | Griffin-Lite | Result |
|---|---|---|
| Audio-to-video latency (H100) | 0.43 s average | Half the next-fastest method |
| Perceptual quality (DOVER) | 1st of 5 | Best |
| Distribution fidelity (FID) | 1st of 5 | Best |
| Talking-head eval (THEval) | 1st of 5 | Clearly best |
| Lip-sync confidence (LSE-C) | 7.27 | 2nd of 5 |
The LSE-C row deserves care, because Tavus flags its own caveat: LSE-C “rewards pronounced mouth movement, including movement past the point where it looks natural, which THEval accounts for.” In other words, the metric Griffin places second on is one that can be gamed by exaggerated mouth motion — and it was also the community’s most common visual criticism. These quality numbers, unlike the VideoFDB tracks, are Tavus’s own measurements against baselines it selected.
The safety hold
Tavus is explicit that the properties that make a HIM a good interface also make it a good deception tool. The official page says: “The same properties that make Human Interaction Models powerful interfaces for natural communications between human and machine allow them to deceive a human into believing it is not AI.” It adds that “further alignment and safety procedures are required for safe release” and that Tavus is working on "safe disclosure features” and with organizations tackling AI safety.
The release decision follows. Griffin-Lite is available only to select trusted testers as a research preview and will not be available for customer use at this time; access is by request form. Tavus says it anticipates “releasing Griffin very soon after these safety concerns are addressed”, and that Griffin “isn’t on the Tavus platform yet” — it will come “once we’ve worked out how to release it safely.” Given that nearly half of a live sample could not tell, and that those who could mostly worked it out inside twenty seconds, a disclosure mechanism that survives a casual conversation is not a nice-to-have.
Because it’s the first model that can be mistaken for a real person, Griffin requires safety considerations before it can be released publicly. The full research preview covers how it works, how we tested it and the safety measures that have to come first.
— @tavus October 1, 2026
What the community said
The launch drew a large response — the lead post alone had roughly 29,500 likes, 3,200 reposts and 11.8 million views (1,180万) within about a day — and the replies split into recognizable camps. These are community reactions, not verified facts, and they are included because they show where the pressure points are. Handle names appear as they do on X.
The skeptics questioned the study loudly. The most-liked critical reply disputed the 48% outright: @willjciolino wrote that there is “0 chance 48% of people believed they were talking to a human” and that it “was easy to spot in the first half a micro second.” A separate thread argued the result is effectively chance: @Acezhang01 wrote that “48% is basically a coin flip… disclosure stops being optional.”
The caution camp read it as a threshold being crossed. @WorldianAI wrote that going “from under 3% to 48% in one jump is the part that gets me, even though it’s the company’s own test”, and that “a live video call was the last thing most of us still trusted to prove there’s a real person on the other end.” Among the most-liked replies, at over 1,300 likes, @mayfer went further: “i think we should prolly pass a law making this illegal. im ok with realtime cartoon characters though.”
The impressed camp focused on the leap. @heyorvian wrote, “i honestly couldn’t believe i wasn’t talking to real human when i tried it, this is truly HIM :)”, and @mihuq wrote, “It gave me chills, it looks too real. Wow.”
Across camps, one technical criticism recurred: the mouth and lip sync. @LLMJunky (about 730 likes) wrote, “The mouth movements are quite weird. It’s cool though, worst it’ll ever be. I don’t agree it looks real though. Close but not quite.” A milder version from @kusailatalit: “still a bit of work to do on the lips movements and latency overall but seems crazy good! gg.” That is the same dimension where the benchmark ranks Griffin second on LSE-C rather than first — the crowd and the metric agree.
The jokes are part of the record too — @litcapital asked whether Griffin could “come to the bars… to crush beers after work” — and so is the dystopia framing from @tedbjorling: “Science fiction unfolding in front of our eyes. Or dystopia. Not sure.” Tavus replied in-voice to many of these, which is where the “Griffin Lite :)… see how we’re improving on Griffin Lite” teaser came from. What the reaction does not provide is independent validation: no reply, quote, or discussion found for this article reproduced the study or ran the benchmark.
Availability and pricing
Availability is the constraint that matters most today: there is no way to buy or call Griffin. There is no model ID, no endpoint, no rate limit, no SLA, no region list, and no published price. Tavus points anyone who wants to build today at the models “150,000 developers and businesses already use” — Phoenix, Raven and Sparrow — which are the predecessors, not Griffin.
For context, Tavus’s existing Conversational Video Interface platform has a published, if cluttered, price list on tavus.io/pricing (checked October 2, 2026). The developer tiers shown include a free tier with 25 minutes of conversational video and a Starter tier at $59/month with 100 minutes and $0.37/min overage; the same page also displays a second set of plan blocks (including a $22 Starter, $397 Growth and $975 Business) that overlap with the first. None of these plans include Griffin. Any figure quoted for Griffin itself is invented — Tavus has published none.
| Option | What you get | Griffin included? |
|---|---|---|
| Griffin-Lite (research preview) | Selected trusted testers only, by request form | This is Griffin |
| Tavus Free (developer) | 25 min conversational video, 5 min video generation, 25 stock replicas | No |
| Tavus Starter ($59/mo) | 100 min conversational video, 3 custom replicas/month | No |
| Tavus Growth ($397/mo) | 1,250 min conversational video, 100+ stock replicas | No |
| Tavus Enterprise | Custom, white-label, SLAs | No |
Limitations
Five gaps stand between the launch and any real deployment decision.
- The Turing study is small and company-run. n=54, one-minute calls, no independent replication, no real-human comparison arm. The 48% is a striking signal, not a settled population estimate.
- The perception lead is partly a comparison artifact. Griffin sees video; its strongest baseline was scored audio-only. NVIDIA’s own paper notes that seeing is not the same as using what you see.
- Long-session behavior is unverified. Tavus says the generator was trained so long rollouts do not drift, but it has published no results for sessions longer than a minute. Real conversations run 10 to 60 minutes.
- The safety documents are missing. No model card, capability-threshold assessment, or misuse evaluation was public at launch.
- Pricing and access are undefined. There is nothing to evaluate on cost, latency at scale, or reliability, because none of it has been offered.
What it means for agent builders
Set aside the access question and the launch still changes how you should think about real-time agents.
Timing is the differentiator, not fidelity. The most useful number in the release is not 48% — it is that a benchmark (VideoFDB) now exists that scores when an agent acts, not just what it says. Turn-taking, backchannels and interruption handling are measurable, and the whole field, including frontier real-time models, scores well below human on them. If you build voice or video agents, that is the dimension to instrument.
Full-duplex is architecture, not a feature flag. You cannot bolt continuous backchanneling onto a cascade of transcribe, then LLM, then synthesize. Griffin’s headline behaviors follow from generating speech and video from the same control signal in one loop. If your product depends on interruption or nonverbal cues, a cascade will structurally limit you.
Design for the ladder, not the launch. Tavus’s own replies telegraph a “Griffin Lite” and a bigger model behind it, and the platform’s existing stack is where anything shippable lives today. Keep building on the documented models and track the appearance of a Griffin row on the Tavus platform.
Treat disclosure as a product requirement. Every serious participant in this space, Tavus included, now says disclosure tooling has to come before release. If your agent can be mistaken for a person, the studiable failure mode is not “did it fool the user” but “could the user reliably find out.”
FAQ
What is Tavus Griffin?
Griffin is Tavus’s first Human Interaction Model (HIM): a full-duplex, video-to-video system that perceives a person’s audio and video, decides when and how to respond, and generates speech and video at the same time. Tavus calls it the first model to pass a real-time video Turing test.
Did Griffin really pass the Turing test?
In Tavus’s own live study, 26 of 54 participants (48%) believed a Griffin-Lite persona was a real person after a one-minute video call, against 1 of 41 (2.4%) on Tavus’s previous stack. It is a striking result, but it comes from a small, short, company-run study with no independent replication and no real-human comparison arm.
What did NVIDIA’s benchmark measure?
NVIDIA’s VideoFDB is the first benchmark for full-duplex audio-visual conversation, scored 0–5 by a language-model judge across 237 real call clips on two tracks. Griffin-Lite scored 3.83 on generation (human 3.92) and 3.73 on perception (human 4.20), first on both against the published baselines.
Can I use Griffin today?
No. Griffin-Lite is a research preview for selected trusted testers, reached through a request form. It is not on the Tavus platform, has no public model ID, endpoint, or pricing, and Tavus says it will not be available for customer use at this time.
How much does Griffin cost?
Tavus has published no price for Griffin, and any figure you see quoted for it is invented. Tavus’s existing Conversational Video Interface platform is priced separately on tavus.io/pricing and does not include Griffin.
What is a Human Interaction Model?
Tavus defines a HIM as “a new class of model designed to understand and generate face-to-face real-time human interaction.” In practice it means one system that listens while it talks, reads expressions and pauses, and generates the whole video frame — rather than chaining separate speech, language and avatar models.
Is Griffin full-duplex?
Yes. Griffin assesses the conversation at regular sub-second intervals and can backchannel, nod, or take the turn while the other person is still speaking, using both audio and video, rather than waiting for the user to stop.
Why is Griffin not released yet?
Because the same realism that makes it a good interface also makes it deceptive. Tavus says further alignment and safety procedures, including “safe disclosure features”, are required before release, and that it is working with AI-safety organizations.
What is the criticism of the launch?
The most common community criticism is the mouth and lip-sync quality — the same dimension where the benchmark ranks Griffin second on LSE-C rather than first. Reviewers also questioned the study’s small sample and Tavus-run methodology, and several argued a model this convincing needs mandated disclosure.
How is Griffin different from Phoenix, Raven and Sparrow?
Phoenix, Raven and Sparrow are Tavus’s existing separation-of-labor models — face rendering, perception and turn-taking — chained in a cascade. Griffin folds perception, conversational decision-making and generation into one real-time video-to-video system. The existing three are what you can build on today.
Sources
Sources checked October 1–2, 2026.
- Griffin: The First Human Interaction Model — Tavus (official product and research page; all capability, study and benchmark claims)
- VideoFDB — NVIDIA and the paper (benchmark definition, baselines, human references)
- Tavus on X — the launch thread (Simon Says, full duplex, cube coach, safety; embedded posts above are quoted in part)
- Plans and Pricing — Tavus (existing platform tiers; checked to confirm Griffin is not listed)
- Community replies on the launch thread, linked inline above; quoted as attributed reactions, not as verified facts.
Related reading: Gemini 4 Argon complete guide, OpenAI DevDay 2026 recap, GPT-6.1 Sol guide, and Codex Security Cloud guide.